Fable 5.2 vs Opus 5.5: Raise Effort Before You Switch Models
Anthropic says to start on Opus 5.5 and switch models last. Give Claude a check, raise effort one level, then try Fable 5.2, which costs about the same as Opus at max in independent tests, not half.
Anthropic priced two ways to run Claude Opus 5.5 on a subset of SWE-bench Pro, a coding benchmark. They differed in effort. That setting tells Claude how much to spend: how long to think, how many tools to call, how often to check itself.
Every task at high passed 95.3%, at $0.29 a task. Every task at low, with only failures run again at high, passed about 97%, at about $0.17, per Anthropic's model guide.
The cheap run plus a retry won.
That result matters for Fable 5.2, Anthropic's bigger model, launched on 2026-11-09. Should it become your default?
No. Anthropic's own advice is to start on Claude Opus 5.5 at medium effort. When a result falls short, give the model a way to check its work, raise effort one level, and move to Fable 5.2 last.
That order matters most to builders who fix a weak result by picking a bigger model.
Fable 5.2, Anthropic's most capable generally available model, lists at $8 per million input tokens and $40 per million output tokens. Opus 5.5 lists at $4 and $20, per the same guide. Cache reads cost $0.20 per million on both.
So a model switch doubles the price of every uncached input and output token, including the ones the bigger model did not need.
Model choice is also only one of the costs. Build to Launch's Claude Code token optimization guide shows how tool output and long sessions pile up before the model matters at all.
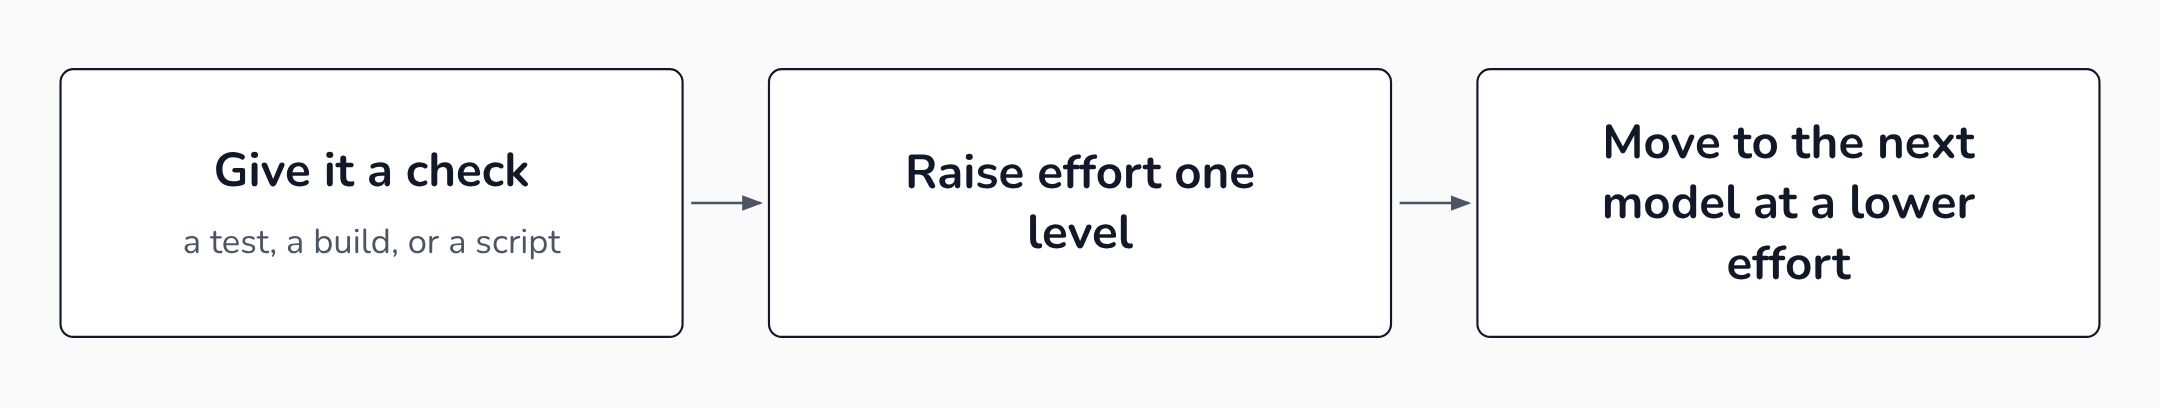 Anthropic's guide puts the model switch last; the check comes first because it makes cheap settings safe.
A check comes first, because the 97% depends on one
The re-run result only works because something marked which tasks failed, and on SWE-bench Pro that something is a test suite.
So the first step in Anthropic's guide is to "check that the model can verify its own work, with a test, a build or a script that calls the endpoint."
A check lets the model see its own mistakes. It also lets you run cheap settings without fear. A miss gets caught.
The Claude Platform cost guide lists the policy in three rows:
- Low, with failures re-run at high: about 97% for about $0.17.
- Medium, with failures re-run at high: about 97% for about $0.24.
- Everything at high: 95.3% for $0.29.
The re-run costs include the failed cheap attempts.
One caveat sits in that same page. Anthropic "computed this policy task by task from the Claude Opus 5.5 effort runs." The page reports no live run of the policy.
A live version needs a check you trust to mark the failures, or the savings go to the wrong tasks.
What to do when you have no test suite
Plenty of work has no automatic check: a new feature, a design, a refactor of untested code.
For that work, Thariq Shihipar of Anthropic describes the loop he uses in Spending your effort.
- Give Claude a spec and ask it to interview you about missing details.
- Implement it on low effort.
- Review it yourself, and iterate on low as needed.
- Verify and test on high effort.
Step 3 makes you the check.
The loop applies the re-run idea by hand. Low effort does the building, cheaply. Your review decides what goes back. High effort, in step 4, is spent once, on verification, after the cheap version exists.
That high-effort pass is also a chance to build the check you were missing. A run that writes tests leaves you a test suite for the next change. That change can then use the automatic re-run.
One effort level is a finer dial than a new model
The Claude Platform effort docs list five effort levels, from low to max. Opus 5.5 defaults to medium.
Each step has a measured price.
On SWE-bench Pro, Anthropic's guide reports Opus 5.5 at medium scored about 2.5 points lower than high, for about 70% of the cost. At low it scored about 8 points lower for about a third of the cost. At xhigh it scored about 1.4 points higher, for 2.5 times the cost of high.
What the extra effort buys, more testing, shows up in one task from Terminal-Bench 3.0, a community-sourced benchmark: a linear-program solver called cli-2ph-simplex.
Opus 5.5 went from 0 of 5 at low to 5 of 5 at high, Anthropic reports.
At low, it checked a few small problems. Then it stopped. At high, it tested random problems against a separate brute-force solver. Then it reworked its search.
In Claude Code, you change effort with /effort, and you switch models with /model, per the model configuration docs:
/effort high
/model fable
Claude Code saves each /effort level per model.
On the API, effort is one field on the request, shown here from the effort docs:
response = client.messages.create(
    model="claude-opus-5-5",
    max_tokens=4096,
    messages=[
        {
            "role": "user",
            "content": "Analyze the trade-offs between microservices and monolithic architectures",
        }
    ],
    output_config={"effort": "medium"},
)
When raising effort stops helping
Effort has a ceiling. The ceiling shows up in the kind of mistake.
Across Terminal-Bench 3.0, more effort cut failures from missed edge cases. But effort "does not fix when the model has the wrong approach," per Spending your effort. A model judge sorted those failure types. Treat the split as approximate.
The study's own counts mostly fit. For Fable 5.1, one of the two models the study ran, going from low to max effort cut "a bug its tests missed" from 40 to 14 of 370 attempts. "Misread a requirement" also fell, from 45 to 26. Only "picked the wrong reading" rose, from 25 to 47. That rise is what the study's point predicts.
The study does not say which labels count as which kind. A rough reading: a failure that more checking would have caught is an edge-case miss, and effort helps with it. A model that keeps choosing the same wrong reading of the task, even at high, has an approach problem.
Anthropic's guide puts the limit in plainer words: a higher effort level "won't give a model knowledge or skill it doesn't have."
So if Opus 5.5 at high keeps choosing the wrong approach, the next model up is the fix. The guide adds one rule for the switch: start the new model at a lower effort than you used on the old one.
Is Fable 5.2 cheaper than Opus 5.5?
On one test, Fable 5.2 costs about half as much. On others, it does not.
The launch headline says Fable 5.2 at high effort matched Opus 5.5 at max on FrontierCode 2.0 for roughly half the cost per task.
That is the strongest case for skipping the order and switching now.
FrontierCode measures "whether a model's code changes would be merged by the maintainers of open-source repositories," per Anthropic's launch post. The Fable 5.2 system card shows where the half comes from. Cognition, which runs FrontierCode's public leaderboard, ran it once per setting. Fable 5.2 at high scored 45.3% at $6.72 a task, against 45.5% at $12.82 for Opus 5.5's best, at max. Each score is "a single result from Cognition with no uncertainty interval."
The comparison point is Opus at max, its most expensive setting. Opus 5.5 defaults to medium.
Independent testers measured both models. They found a smaller gap, or none.
Table: Fable 5.2 against Opus 5.5, cost per task
| Who measured | Fable 5.2 | Opus 5.5 | Result |
|---|---|---|---|
| Cognition, FrontierCode 2.0 | high: 45.3%, $6.72 | max: 45.5%, $12.82 | about level, about half the cost |
| Artificial Analysis, index of nine tests | high: $9.08 | max: $10.04 | Fable scores higher, costs about 10% less |
| Vals AI, Terminal-Bench 4.0 | high: 65.15%, $14.56 | max: 65.15%, $12.04 | tied, Fable costs about 21% more |
| Artificial Analysis, index of nine tests | medium: $3.80 | medium: $2.45 | at default settings, Opus costs less |
The half-cost figure holds on one benchmark run by one company; at default settings, Opus 5.5 is the cheaper model.
The Artificial Analysis comparison scored Fable 5.2 at high 62 on its Intelligence Index, against 59 for Opus 5.5 at max. Its own FrontierCode run confirmed the score side: Fable at high 49.1%, Opus at max 46.4%. Across its whole index, Fable at high cost $9.08 a task. Opus at max cost $10.04. The cost side did not hold at half.
So the large saving rests on one code-change benchmark run.
Vals AI's Terminal-Bench 4.0 covers "frontier-difficulty terminal tasks across software, science, ML, operations, hardware, security, and media." There the two tied. Fable cost more.
Mervin Praison, a builder, gave both models three of his own tasks, including a cron parser checked against 41 hidden tests. He calls these single runs, one sample. Fable at high finished all three for $0.73. Opus at max finished one, for $2.60, and twice ran out of a 64,000-token limit before writing an answer. He also ran Opus at its default, medium. It passed all 41 tests for 8 cents and cost less than Fable on every task.
Anthropic's launch post agrees. "For most coding and knowledge tasks," it says, "we recommend that users start with Claude Opus 5.5."
When is Fable 5.2 worth it?
Fable 5.2 earns its price at one point: where you would otherwise push Opus 5.5 past high.
"Past high, one more effort level can cost as much as a bigger model," Anthropic's guide says. "If you're past high, test the next model up at a lower effort instead."
The Artificial Analysis numbers show the trade. Opus 5.5 cost $3.46 per index task at high and $10.04 at max, while Fable 5.2 at medium cost $3.80, about what Opus costs at high.
On the index's Engineering category, Fable at medium matched Opus at max, 65 to 65. On Terminal-Bench-Science, a set of science tasks run in a terminal, it scored 60.5% to Opus's 59.0%. Anthropic's launch post calls Humanity's Last Exam "a test of expert-level academic knowledge and reasoning." HLE-Diamond is a version of it. There Fable came close, 66.3% to 67.9%.
Anthropic also reports Fable 5.2 matching Opus 5.5's top score on Humanity's Last Exam at low effort for under a tenth of the cost, in its launch post. That figure is Anthropic's own. On Artificial Analysis's HLE-Diamond, Fable at low scored 60.8% against 67.9% for Opus at max.
At medium, coding is the exception to those matches. On FrontierCode, Fable 5.2 at medium scored 37.6%, well under Opus's best of 45.5%, the system card reports. On that test, Fable needed high to catch up.
Anthropic's guide names the work where Fable pays: major refactors and migrations, architecture planning, deep research, scientific or quantitative analysis, and long unattended runs.
Max effort is where more spending stops paying, on both models.
On FrontierCode, Fable 5.2 at max scored 45.7% at $44.70 a task, below its own xhigh score of 49.1% at $14.19, per the system card.
High settings also need room. The effort docs say to set a large max_tokens, because that one number caps thinking and answer together. When attempts end at the cap, the cost guide says to raise max_tokens to 64,000.
Hit the cap and you pay for thinking with no answer, as Praison's Opus max runs did.
Try the order on your next miss
- Keep Opus 5.5 at medium as your default in Claude Code and on the API.
- Before changing anything, add a check: a test, a build, or a script that calls the endpoint.
- If you have a check and run many tasks, run them at low and re-run only the failures at high.
- If you have no check, use the loop: implement at low, review it yourself, verify at high.
- When a result still falls short, raise effort one level and run it again.
- If Opus at high keeps choosing the wrong approach, try Fable 5.2 at medium, one level below the high you used on Opus, on that task only. For coding, test high as well. In the one FrontierCode run, Fable at medium trailed.
- Price your hardest tasks, not your typical ones. On one 20-problem benchmark in Anthropic's guide, two problems carried 43% of the spend.
FAQ
What effort level does Claude Code use by default?
Fable 5.2, Opus 5.5, Sonnet 5.5 and Haiku 5.5 all default to medium in Claude Code, according to Claude Code's model configuration docs. On the API, Fable 5.2 defaults to high. Run /effort to change the level. Each model keeps its own saved level.
Should I set effort to max?
Max makes a poor default. Claude Code applies max to the current session only, unless you set it with the CLAUDE_CODE_EFFORT_LEVEL environment variable, as the same docs explain. On FrontierCode, Fable 5.2 scored lower at max than at xhigh for about three times the cost, per the system card.
Can I set a different effort for a subagent?
Yes. Claude Code reads an effort field in a skill or subagent markdown file and uses it when that skill or subagent runs, the docs say. That lets a test-running subagent work at low while the main session stays at medium.
Sources
- Addy Osmani, Which Claude model should you build with? Fable, Opus, Sonnet, or Haiku, claude.dev, 2026-11-09
- Anthropic, Claude Fable 5.2 and Mythos 5.2, 2026-11-09
- Claude Platform Docs, Optimizing for cost and intelligence, accessed 2026-11-11
- Thariq Shihipar, Using Claude Code: Spending your effort, claude.dev, 2026-09-25
- Anthropic, Claude Fable 5.2 and Mythos 5.2 System Card, 2026-11-09
- Claude Code Docs, Model configuration, accessed 2026-11-11
- Claude Platform Docs, Effort, accessed 2026-11-11
- Build to Launch, Claude Code Token Optimization Guide, 2026-04-14
- Artificial Analysis, Claude Fable 5.2 vs Claude Opus 5.5, accessed 2026-11-11
- Vals AI, Terminal-Bench 4.0 leaderboard, updated 2026-11-09
- Mervin Praison, Claude Fable 5.2 vs Opus 5.5: What It REALLY Costs, YouTube, 2026-11-09
Links
- Which Claude model should you build with? Fable, Opus, Sonnet, or Haiku (documentation)
- Claude Fable 5.2 and Mythos 5.2 (documentation)
- Optimizing for cost and intelligence (documentation)
- Using Claude Code: Spending your effort (documentation)
- Claude Fable 5.2 and Mythos 5.2 System Card (documentation)
- Model configuration (documentation)
- Effort (documentation)
- Claude Code Token Optimization Guide (article)
- Claude Fable 5.2 vs Claude Opus 5.5 release comparison (article)
- Terminal-Bench 4.0 leaderboard (article)
- Claude Fable 5.2 vs Opus 5.5: What It REALLY Costs (article)
New guides on building with AI come in the Build to Launch newsletter.
More guides
Vibe Coding Development Services: A €3,000 and a €12,000 Quote Can Buy the Same Screens
The screens in an agency quote are what your AI tool already builds. Compare vibe coding quotes on the five lines a prototype leaves out: data locked to each user, a security review, deployment, code ownership and fixes after handoff.
How to Build Claude Interactive Apps That Still Work When Claude Withholds the New Features
Claude interactive apps are MCP Apps: a tool on your remote MCP server opens a sandboxed web view in the conversation. The inline view reaches every install; the side panel, app tools, entry points and embedded sites added on 2026-11-10 depend on each user's organization, interface and listing, so build them as upgrades.
Claude Fable 5.2 Prompting Guide: Remove Old Lines First, Then Add Only What You Measure
Claude Fable 5.2 follows the text it is given closely. Set effort first, cut lines written for older models, then add Anthropic's tested text only for behaviors you see.